>>
Technology>>
Artificial intelligence>>
Beyond Bigger Models: How Shua...Beyond Bigger Models: How Shuangquan Lyu’s Research Is Making AI More Efficient, Adaptable, and Trustworthy
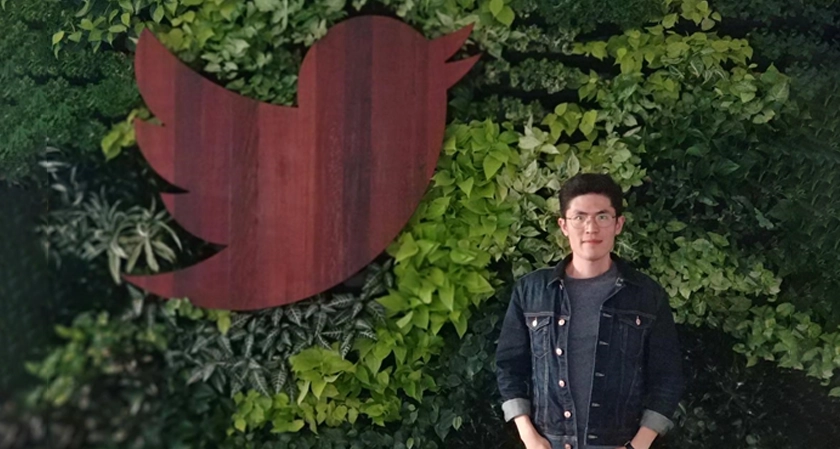
From helping language models learn with limited data to improving long-form video generation, the U.S.-based AI researcher is exploring ways to overcome some of the most persistent technical limitations of modern artificial intelligence.
Artificial intelligence has entered an era of extraordinary technological progress. Large language models can generate sophisticated responses, and generative AI systems can produce increasingly realistic images and videos. Yet as these systems become more powerful, a fundamental question remains: how can advanced artificial intelligence become more efficient, dependable, and accessible without continually increasing the data and computing resources required to develop it?
For Shuangquan Lyu, a U.S.-based artificial intelligence researcher and experienced machine learning engineer, addressing these limitations has been a recurring focus of his scholarly work.
With a Master's degree in Software Engineering from Carnegie Mellon University and experience developing large-scale machine learning systems at Twitter and Meta, Lyu combines industry engineering expertise with an active research record pursued alongside his professional career. His published research spans low-resource language processing, transfer learning, multimodal generative AI, and efficient machine learning, with first-authored studies examining how existing foundation models can be adapted to new tasks and more demanding workloads.
Although these studies address different applications, they share a central objective: improving the adaptability, computational efficiency, and reliability of artificial intelligence through more effective learning strategies, model optimization, and evaluation.
Teaching Large Language Models to Learn More with Less Data
Modern large language models have demonstrated impressive capabilities in language understanding and generation. However, their performance can be less reliable when applied to underrepresented languages, specialized professional domains, or tasks where annotated examples are limited or expensive to obtain.
These constraints affect organizations seeking to deploy AI for specialized applications. While an enterprise or research institution may have access to an existing foundation model, adapting that model to a new language or domain can require substantial additional training resources.
Lyu's first-authored paper, "Transferable Modeling Strategies for Low-Resource LLM Tasks: A Prompt and Alignment-Based Approach," published at the 2025 IEEE International Conference on Artificial Intelligence Technologies and Applications, investigates how to overcome this challenge.
The research introduces a framework combining knowledge transfer, semantic alignment, soft prompt tuning, and parameter-efficient fine-tuning. Rather than requiring developers to retrain an entire large language model, the approach adapts lightweight trainable components while preserving much of the model's previously acquired knowledge.
A central element of the framework is a knowledge-alignment mechanism designed to help models recognize semantic relationships between source and target languages or tasks. Together with selective parameter updates, the method enables existing pretrained representations to be reused under limited-data conditions.
On the MLQA multilingual question-answering benchmark, the proposed method achieved an F1 score of 83.6, compared with 80.4 for the VECO baseline. On the XQuAD benchmark, it achieved an Exact Match score of 75.8, while reaching 89.4% accuracy on the PAWS-X sentence-pair classification benchmark, compared with VECO's 87.2%.
The study also examined training stability and the use of synthetic data to supplement limited labeled examples. The results suggested that moderate amounts of synthetic training data could improve performance, while excessive augmentation might introduce distributional drift and reduce model effectiveness.
These findings highlight an important consideration in developing adaptable AI systems: increasing the amount of training data or the number of trainable parameters does not necessarily produce the best results. The effectiveness of knowledge transfer and the stability of the adaptation process also matter.
Lyu has contributed to related research on few-shot learning, a technique that enables models to learn new tasks from limited examples. In the coauthored study "A Hybrid Model for Few-Shot Text Classification Using Transfer and Meta-Learning," the researchers combined pretrained model knowledge with meta-learning to improve text classification under data-scarce conditions.
Experiments on the 20 Newsgroups dataset showed that the proposed framework achieved 60.1% classification accuracy in its most data-limited experimental setting, outperforming the evaluated conventional machine-learning and deep-learning baselines, including an LSTM model that achieved 56.9%.
Although benchmark improvements do not automatically establish performance across every real-world application, these studies provide evidence that transfer learning, task adaptation, and carefully designed optimization techniques can improve model performance when annotated data is scarce.
The potential applications are broad. More efficient language-model adaptation could support multilingual information services, specialized enterprise knowledge systems, educational technologies, and other settings where organizations may lack the extensive datasets required for conventional model training.
Addressing the Computational Challenges of Generative Video AI
Recent text-to-video diffusion models have made substantial progress in generating realistic short clips. However, longer video sequences remain difficult to produce and edit consistently. Models may encounter GPU memory limitations, visible transitions between generated segments, and gradual changes in appearance or motion over time.
These difficulties become particularly apparent in two types of video editing: inpainting, which reconstructs or modifies selected regions within a video, and outpainting, which extends visual content beyond the original frame boundaries.
In the first-authored paper "Unified Long Video Inpainting and Outpainting via Overlapping High-Order Co-Denoising," accepted at the 2026 International Joint Conference on Neural Networks, Lyu and his collaborators introduced a unified framework designed to address these problems.
The research builds on the Wan 2.1 video foundation model and combines three techniques: Low-Rank Adaptation (LoRA), overlapping temporal processing windows, and higher-order diffusion sampling.
Instead of fine-tuning the entire video-generation model, the framework trains lightweight adapters that enable the model to perform mask-conditioned editing. During inference, longer video sequences are divided into overlapping windows. The model then applies second-order Heun sampling and Hamming-weighted blending to improve continuity between neighboring segments.
This design allows the system to process long video sequences without requiring all frames to be handled simultaneously, keeping memory requirements bounded by the selected window size.
The researchers evaluated the method on InpaintBench, a benchmark comprising 30 real-world videos ranging from 81 to 300 frames. The proposed framework reported improvements in background preservation, temporal consistency, and text alignment compared with the evaluated Wan 2.1 variants and VACE.
For example, it achieved an LPIPS score of 0.121, compared with 0.125 for VACE, where lower scores indicate better preservation of existing visual content. Its CLIP score reached 29.4, compared with VACE's 28.4, indicating improved alignment with the textual editing instructions under the study's evaluation protocol.
The researchers also demonstrated video editing across sequences of up to 800 frames, illustrating the framework's ability to extend beyond the relatively short sequences typically supported by many foundation video models.
An important aspect of this approach is that it seeks to overcome computational limitations through algorithmic design rather than relying exclusively on larger models or additional hardware.
Although additional testing would be required to assess its performance across a wider variety of video-editing workloads, the framework suggests possibilities for AI-assisted film production, digital media creation, advertising, visual design, and simulation.
Connecting Academic Research with Real-World Machine Learning Systems
At Twitter, he worked on large-scale recommendation technology, including the company's Who-to-Follow account recommendation system. His responsibilities included developing machine learning pipelines, improving candidate retrieval and ranking mechanisms, and optimizing system performance and efficiency.
He also contributed to Twitter's initiative to release portions of its recommendation algorithms as open-source software. The publicly available Twitter recommendation-algorithm repository includes components of the company's production recommendation infrastructure, allowing researchers and developers to examine approaches used to support large-scale personalized information systems.
At Meta, Lyu further developed his expertise in applied artificial intelligence through work on Instagram advertising quality and recommendation-related machine learning models. His work included neural network optimization, large language model-assisted data annotation, multimodal content understanding, and improvements to the computational efficiency and stability of production machine learning infrastructure.
In large-scale production environments, model accuracy is only one measure of success. Machine learning systems must also satisfy constraints involving latency, computational cost, serving capacity, reliability, and continuously changing data distributions.
Alongside his industry work, Lyu has continued to participate in academic research and scholarly publication. His research record also includes a coauthored study on unsupervised visual representation learning, "Multi-Scale Adaptive Clustering and Local Consistency Learning for Unsupervised Clothing-Changing Person Re-Identification," published in IEEE Transactions on Information Forensics and Security in 2026.
That study investigated methods for improving visual recognition without requiring manually annotated identity labels or complex external preprocessing. It provides another example of research exploring how machine learning systems can perform effectively with reduced annotation requirements and streamlined architectures.
In addition to conducting research, he has participated in academic peer review for journals and international conferences, including IEEE Transactions on Circuits and Systems for Video Technology and the IEEE World Congress on Computational Intelligence.
Why More Efficient and Reliable AI Matters
The ability to adapt existing AI systems to new tasks without extensive retraining can be particularly valuable when labeled data is limited. Similarly, techniques that enable advanced generative models to handle complex workloads without proportionally increasing memory requirements can help reduce barriers to practical deployment.
Reliability is another important consideration. The U.S. National Institute of Standards and Technology's AI Risk Management Framework identifies characteristics such as reliability, explainability, and transparency as important elements of trustworthy AI systems.
Lyu's published studies approach these issues from different directions. His language-model research investigates how knowledge transfer and lightweight adaptation can improve performance under limited-data conditions. His generative-video research examines how existing foundation models can be extended to longer and more demanding workloads while controlling computational requirements.
Although the results have been demonstrated in specific experimental settings, the underlying techniques address challenges shared by a wider range of AI systems.
The potential value extends beyond major technology companies. Startups, smaller businesses, research institutions, and public-interest organizations may benefit from methods that make advanced AI capabilities more practical without requiring the same level of training data or computing infrastructure as the largest industry participants.
At the same time, publicly available research can support further investigation by researchers and engineers working on related problems, helping technical advances circulate beyond their original development environments.
Through his published research in low-resource language processing and generative video, together with his experience developing production-scale machine learning systems, Shuangquan Lyu has contributed to this effort, demonstrating approaches that could help make advanced artificial intelligence more efficient, adaptable, and accessible across a wider range of real-world applications.


Comments